Qualcomm has finished first-pass silicon validation of High Bandwidth Compute, its attempt to reach memory bandwidth without leaning on HBM stacks. Engineers confirmed that memory reads, writes, and near-memory compute all function on the design, which debuts in the Dragonfly AI250 accelerator, slated to sample during the first half of 2027.
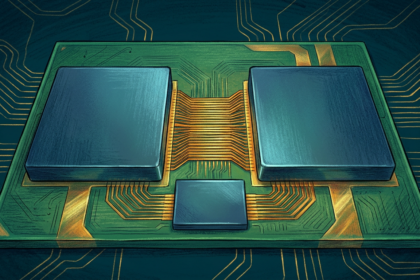
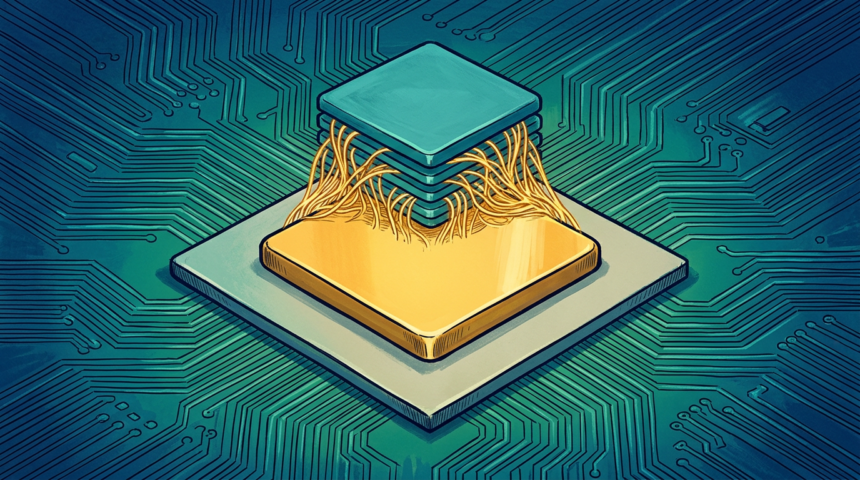
The approach sits LPDDR dies atop the compute die, so data is handled where it is stored. Conventional HBM instead wires separate stacks to a processor through an ultra-wide interface, and that difference drives the power and cost arguments.
Numbers measured against published specs
Bandwidth per watt comes in above five times HBM4, a comparison drawn from HBM4’s published specifications rather than tested silicon. Qualcomm also cites 18 times the bandwidth of external LPDDR5X without publishing absolute figures.
Packaging may prove the sharper edge. HBM demands CoWoS or EMIB to marry stacks, dies, and controllers, and that capacity is the industry’s tightest constraint. Pushing more compute beneath the memory cuts what the main processor must move, which opens the door to a plain 2D organic substrate.
Cost tracks the same logic. HBC draws on standard LPDDR5X dies instead of DRAM built specifically for HBM, and is expected to pack more capacity per package than today’s HBM4 parts.
Qualcomm has named no suppliers. Korean coverage has tied Samsung and SK hynix to the effort, with TSMC expected to handle integration and advanced packaging, but none of the three has confirmed an arrangement.
A second generation, reserved for the AI300, is pitched at 54 times the effective bandwidth of the LPDDR5X-based AI200, with samples due in 2028.