For a decade the server processor race was won on core counts. Nvidia’s CPU team now argues that approach broke something agents need, and it is building the opposite.
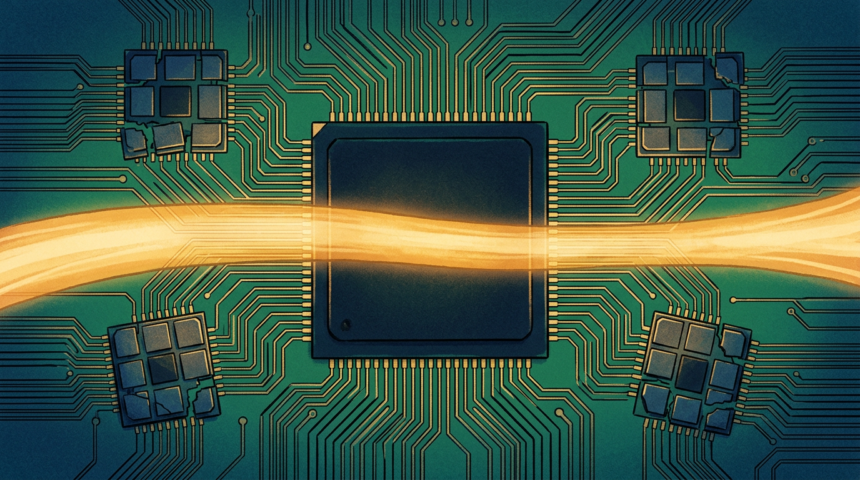
Speaking to Wccftech in an interview published Oct 18, engineers behind the Vera CPU said hyperscale economics pushed x86 vendors from monolithic dies to multiple chiplets to pack more cores per socket. That density kept throughput rising but cost per-core speed and each core’s access to full memory bandwidth, an effect the company calls a chiplet tax.
Agents wait on the CPU
Agentic workloads break the assumption. Tool calls, sandboxed code execution, KV-cache management and result analysis all run on the CPU, repeatedly, between inferences. If host-side work stalls, accelerators idle and the whole agent slows.
Vera answers with a monolithic compute die holding 88 in-house Arm cores and 164MB of unified L3 cache. Spatial Multithreading puts two threads on each core with dedicated resources for worker and input-output threads, so background chores do not preempt work in flight.
The company claims 3.4TB/s of bisection bandwidth, roughly three times a leading x86 part in its comparison, plus LPDDR5X controllers, NVLink-C2C and CXL 3.1 support. It reports a 1.6 times geometric-mean advantage over x86 on sequential agent tasks, from internal SPEC CPU runs in July that were not independently verified.
The tradeoff is real. Monolithic dies cost more to build at large area and cap how many cores fit. Nvidia is betting that for agent hosting, latency on a critical path matters more than renting the cheapest core.
The company has also begun positioning Vera as a standalone rack rather than only a host for GPUs, a shift that would put it against the server CPUs it currently feeds.