Researchers at the National University of Singapore have proposed CHIPSMORE, an accelerator that splits inference work between two kinds of compute-in-memory chiplets instead of routing everything through a single array. The paper appeared in August.
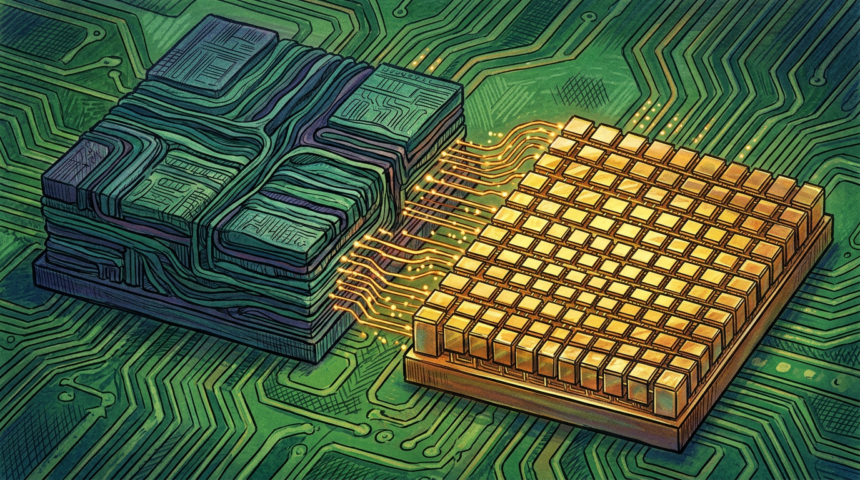
The design pairs analog compute-in-memory built on resistive RAM with digital compute-in-memory built on static RAM. Analog arrays are dense and efficient for matrix multiplication, while digital blocks are more precise and better suited to the low-rank adaptation paths used to fine-tune models. A programmable interconnect between processing elements lets the chip steer work to whichever block fits the request.
That split matters because serving many simultaneous requests forces hardware to juggle two different workloads. Base-model inference is throughput-bound and repetitive. Adapters change weights and shapes on the fly. Systems tuned for one usually pay a penalty on the other.
CHIPSMORE is described as multi-mode, meaning it covers both regimes across varied workloads without falling back to a host accelerator. The authors present the work as an architecture study. No fabrication results, area figures or power measurements accompanied the abstract.
Data movement, not arithmetic, now dominates the energy cost of large-model inference, which is why pushing compute into memory has drawn both startups and established memory makers. Turning the idea into manufacturable silicon remains the open question.