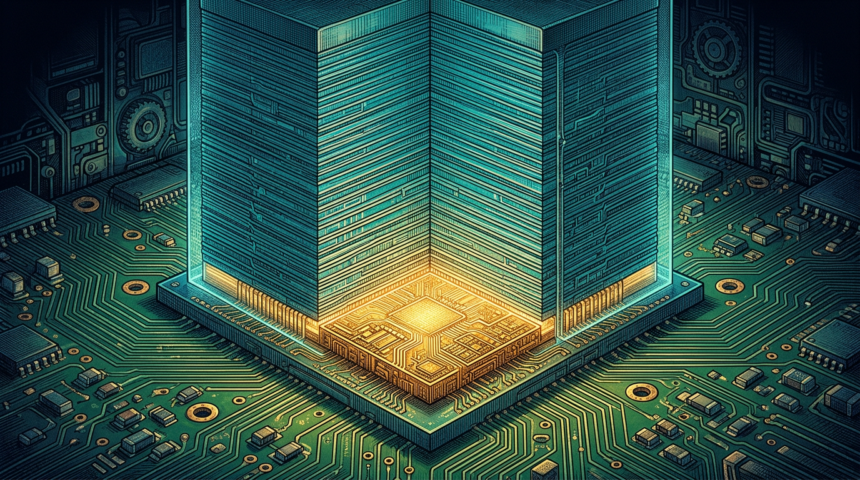
Nvidia wants to stop wasting accelerator silicon on memory control. Its new NVHBM architecture moves the memory controller off the compute die and into the base of the HBM stack, freeing area for actual computation.
The design is part of the NVLink Fusion program that lets hyperscalers build semi-custom XPUs on Nvidia’s rack-scale platform. Compared with standard HBM4E, Nvidia says the approach lifts memory bandwidth by up to 30%, and power draw on the memory side falls as much as 15%.
The compute die gains up to 25% more usable area, according to Nvidia, and several memory vendors are expected to validate the design. That gives buyers a standard implementation that cuts the engineering work of qualifying high-bandwidth memory across suppliers.
Amazon’s Annapurna Labs is the first collaborator to sign on. Its next accelerator family, Trainium4, is slated to adopt NVLink Fusion, putting Amazon-built silicon and Nvidia GPUs on the same rack-scale fabric, with the two companies also cooperating on NVHBM itself.